

Trainium2 availability turned chip claims into an instance-design question
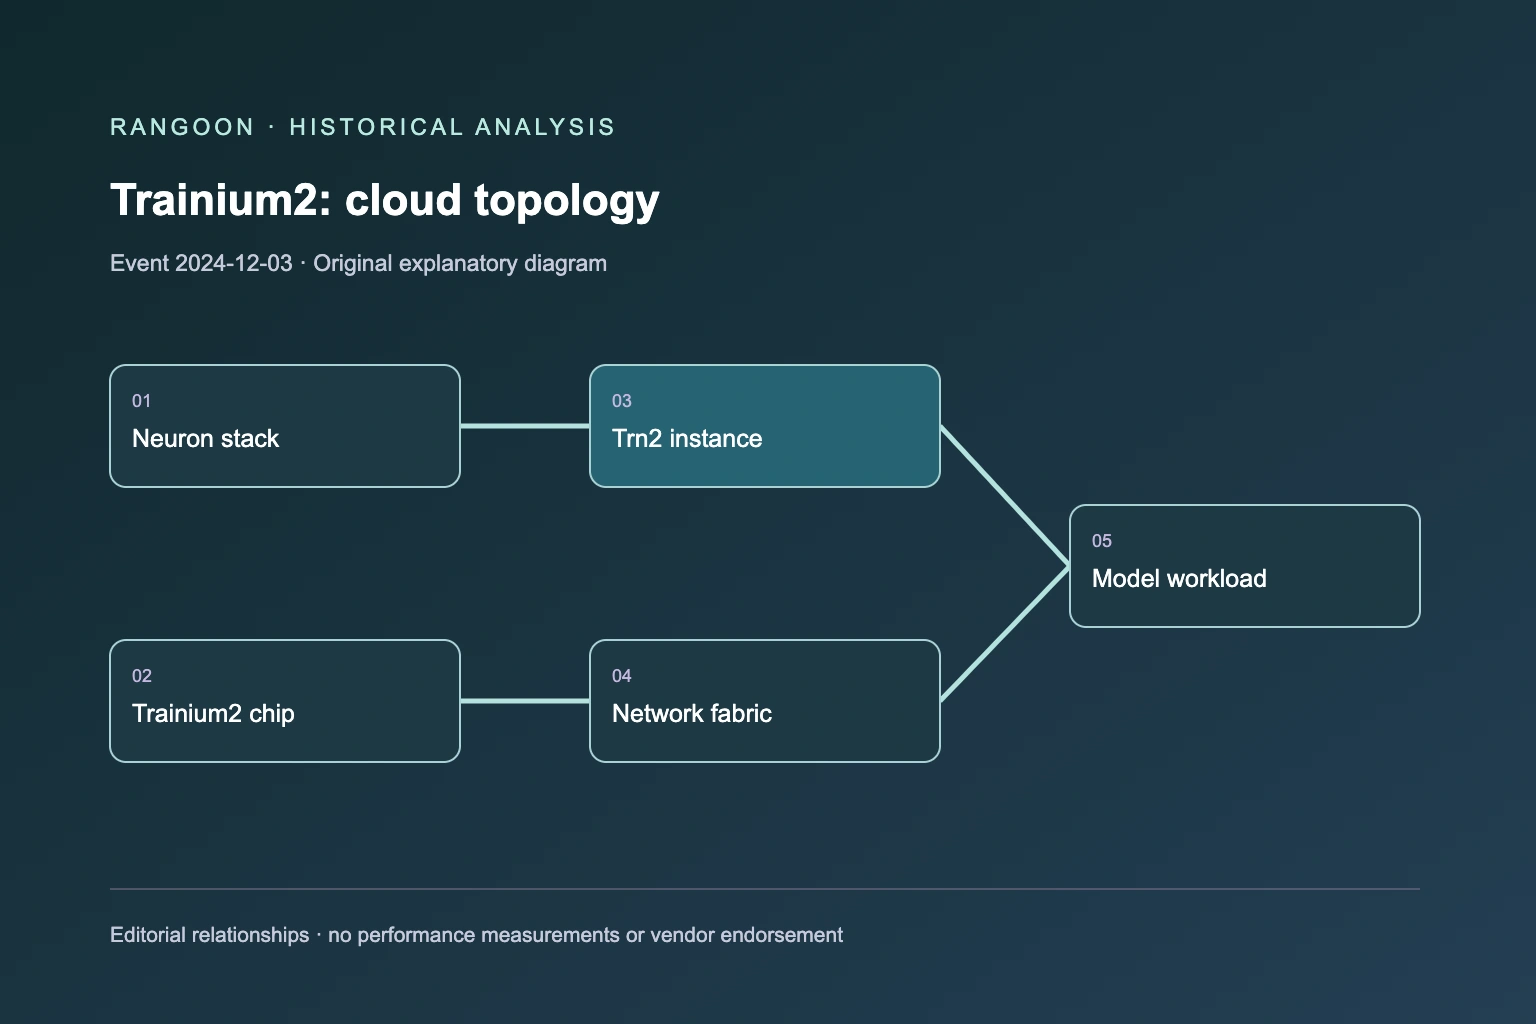
AWS made Trainium2-backed Trn2 instances generally available in December 2024, pairing an accelerator launch with instance, interconnect and capacity-planning choices.
Historical reporting: AWS announced general availability of Trainium2-powered EC2 Trn2 instances on December 3, 2024. Price-performance, scale and future-cluster statements below are attributed to AWS and are not independent workload measurements.
Key takeaways
- Trainium2 arrived as an EC2 instance family and a scale-up server design, not as a standalone chip purchase.
- NeuronLink and EFA make topology, model parallelism and failure handling central to capacity planning.
- Vendor price-performance claims need an equivalent model, precision, batch and service-level comparison.
General availability applied to Trn2 instances[source 1][source 2]
AWS announced the general availability of Trainium2-powered Amazon EC2 Trn2 instances on December 3, 2024, alongside a preview of Trn2 UltraServers and a Trainium3 announcement. The release described Trn2 as an instance for training and deployment, rather than a separately purchased accelerator. Its listed general-availability configuration was trn2.48xlarge through EC2 Capacity Blocks for ML in US East (Ohio).
AWS said a Trn2 instance combines 16 Trainium2 chips using NeuronLink and reported 20.8 peak petaflops. It also compared price performance with its P5e and P5en GPU instances. Those figures and comparisons are AWS claims with the company’s selected configurations. They do not predict throughput, availability or cost for another model, reservation term, region or request pattern.
The scale-up unit was larger than one instance[source 1][source 2]
The announcement introduced Trn2 UltraServers as four Trn2 servers connected through NeuronLink, for 64 Trainium2 chips. AWS described that as a single scale-up node and reported 83.2 peak petaflops. It also described a separate scale-out layer: third-generation Elastic Fabric Adapter networking for the planned Project Rainier UltraCluster. The two layers serve different engineering questions.
Within a node, the concern is how a model’s weights, activations and communication are partitioned across chips. Across nodes, the concern shifts to collective traffic, placement, stragglers and recovery. A system can have ample arithmetic capacity while underperforming if model parallelism, input staging or an all-reduce pattern does not match the available fabric.
Analysis: price performance needs a service denominator[source 1][source 2]
A useful comparison names the delivered unit: completed training run, accepted tokens at a latency target, or evaluated examples per dollar. Then hold model revision, precision, context length, batching, retry behavior and utilization policy constant. A peak-compute comparison cannot settle that question, because serving systems spend time on input processing, decoding, data movement and queueing as well as matrix operations.
Record both the cloud bill and the operating assumptions that created it. Capacity Blocks, on-demand instances, storage, cross-zone traffic, engineering time and idle headroom can change the total. This is independent operational analysis. It does not assert that a Trn2 deployment will be cheaper or faster than a GPU deployment without a workload-specific test.
Analysis: make topology part of the release record[source 1][source 2]
Before moving a model to a new accelerator family, freeze a small release record: framework and compiler versions, model format, distributed strategy, instance count, region, data path, benchmark inputs and pass criteria. Include an interruption test. A result that cannot resume cleanly after one worker disappears may be unsuitable for a long training job even if its best-case speed is attractive.
The December event established an AWS product-availability milestone. It did not prove that every training stack was portable, that Project Rainier was complete, or that a specific organization’s model would meet its production objective. Current service availability, quotas and pricing need separate confirmation at the time of deployment, as do support ownership and regional recovery options.
Sources
Continue reading
Related reading
 News analysisAWS said Project Rainier became operational, separating a running Trainium2 cluster from its next scaling target3 min read
 News analysisAWS Trainium3 availability put scale-up and scale-out claims on separate ledgers3 min read
 News analysisTensorRT-LLM 0.17 added Blackwell and an experimental PyTorch workflow3 min read