OLMo 2 32B made fully open scaling a training-budget record
Ai2 released OLMo 2 32B on March 13, 2025 and described open training artifacts plus reported comparisons. A scale claim needs compute, data, checkpoint, and scorer context.
Historical reporting: Ai2’s March 13, 2025 OLMo 2 32B post announced the model; the OLMo 2 32B Instruct model card provides a separate technical record. The analysis below is original editorial analysis; it does not claim present availability, performance, or support.
Key takeaways
- On March 13, 2025, Ai2 announced OLMo 2 32B and described it as a fully open 32-billion-parameter model, adding a 32B size to the OLMo 2 family.
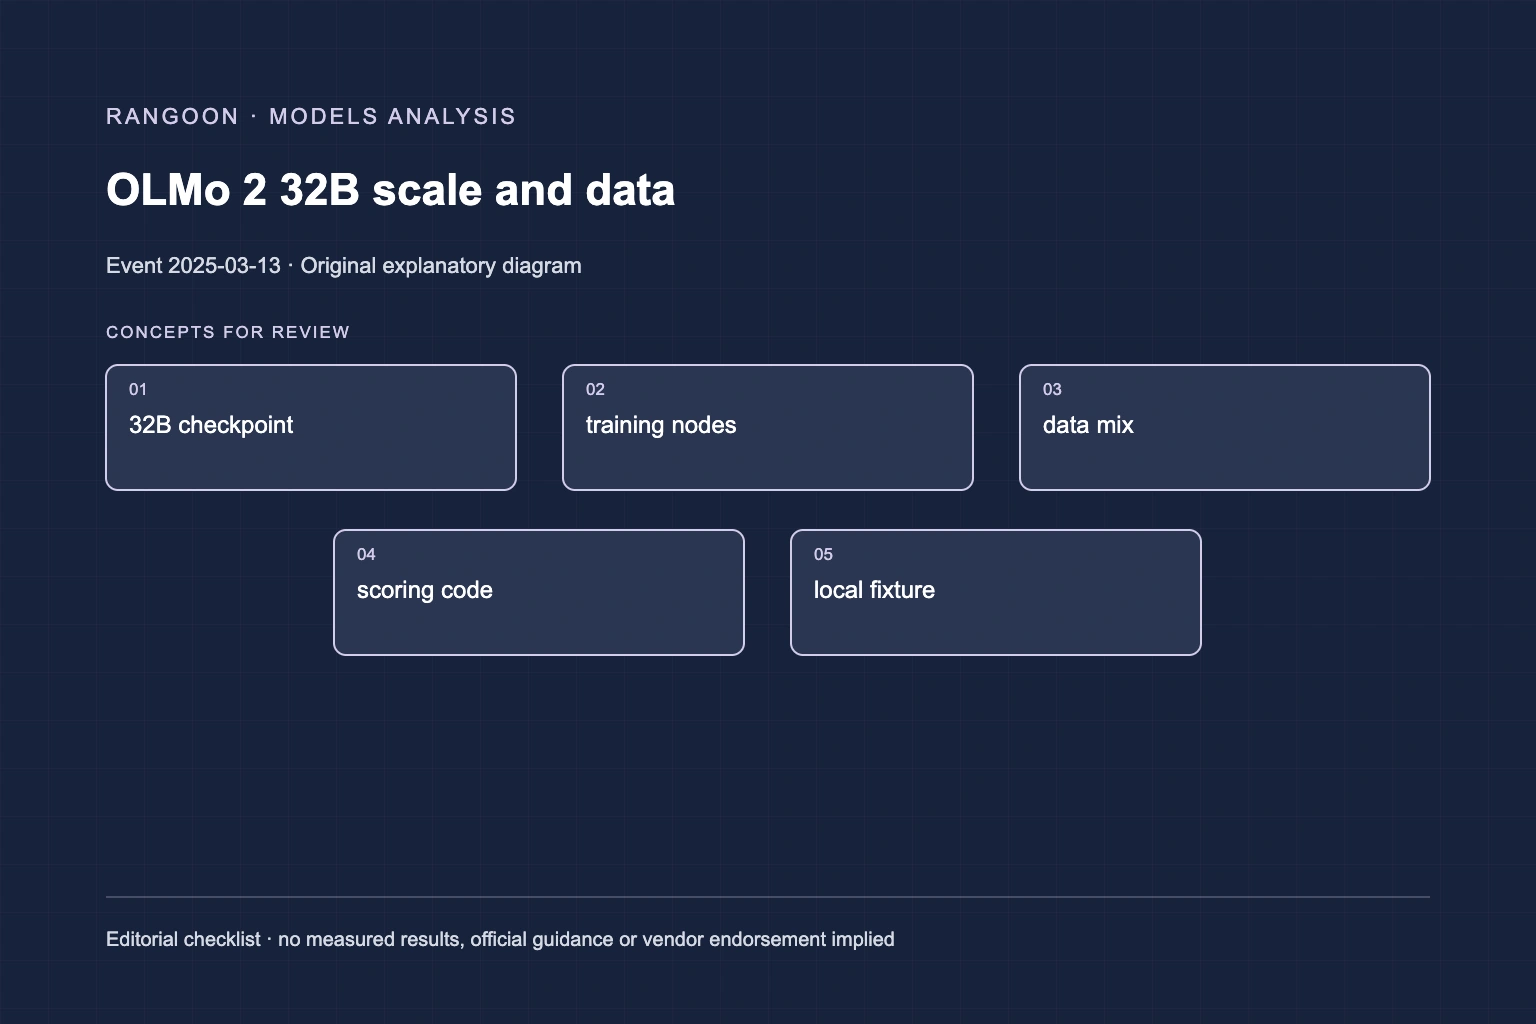
- For a model-scale claim, record parameter count, active architecture where relevant, data mixture, token count, compute layout, training duration, checkpoint selection, and post-training process.
- The March 2025 sources document Ai2’s OLMo 2 32B release and reported claims. They do not independently establish a current score, cost, or deployment fit.
What Ai2 announced[source 1][source 2]
On March 13, 2025, Ai2 announced OLMo 2 32B and described it as a fully open 32-billion-parameter model, adding a 32B size to the OLMo 2 family. The post made supplier-reported comparisons with GPT-3.5 and GPT-4o mini and discussed the release’s training openness. The headline comparison is not enough without its stated evaluation conditions.
Ai2’s OLMo 2 32B Instruct model card separately identifies the released artifact and its technical context. That record helps locate a technical claim, while the launch post establishes the event date. It does not prove a third party can reproduce a benchmark with different hardware, data access, or code revisions.
Editorial analysis: treat training scale as evidence
For a model-scale claim, record parameter count, active architecture where relevant, data mixture, token count, compute layout, training duration, checkpoint selection, and post-training process. These fields do not make results comparable by themselves, but they define what was actually built.
A release can report that a model fits a named hardware setup under stated conditions. Local serving depends on the weight format, context cache, quantization, batching, runtime, and concurrency. Measure those separately before making a capacity decision.
Editorial analysis: reproduce the scorer before comparing scores
Benchmark comparison needs the exact dataset revision, prompt protocol, sampling policy, answer extraction, and scoring code. A change in any one of these can produce a different number while leaving model weights untouched. Preserve supplier and local results as separate observations.
Use a small adversarial fixture set beside broad benchmarks. It reveals schema failures, citation errors, instruction drift, and domain-specific weaknesses that a general aggregate may not expose.
Editorial analysis: make the cost basis auditable
When an adoption discussion cites lower training cost or smaller scale, attach the method and date used for the calculation. Do not compare unnormalized provider claims as if they were a common accounting report.
Ai2’s March release is a historical data point about OLMo 2 32B. It should not be used to imply a present benchmark position or current serving economics.
Editorial analysis: retain the release boundary
The March 2025 sources document Ai2’s OLMo 2 32B release and reported claims. They do not independently establish a current score, cost, or deployment fit.
A scale comparison should resist simple parameter arithmetic. In a hypothetical procurement review, one candidate has a lower parameter count but requires a longer output budget and more retries; another uses more memory but finishes the accepted task reliably. Measure the full path: weight footprint, cache growth, concurrency, energy or infrastructure assumptions where available, reviewer corrections, and task completion. Then attach the date and method for each calculation. This makes claims about training efficiency or model scale auditable without pretending that one public comparison settles local economics. The scenario is original analysis; it is not a measured cost report for OLMo 2 32B.
The final comparison should retain uncertainty ranges and unmeasured factors. A headline parameter count or reported benchmark cannot replace a capacity plan that exposes its assumptions.
Sources
- Ai2: OLMo 2 32B (March 13, 2025)
- Ai2: OLMo 2 32B Instruct model card
Continue reading