Amazon released SOP-Bench for agent evaluation on business procedures
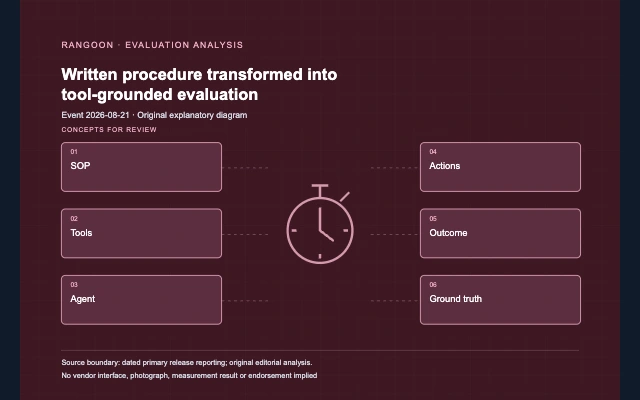
Amazon released SOP-Bench on August 21, 2026, combining expert-authored procedures, tools and ground-truth task outcomes across business domains.
Read analysisInsight tag
15 related stories.
Amazon released SOP-Bench on August 21, 2026, combining expert-authored procedures, tools and ground-truth task outcomes across business domains.
Read analysisMicrosoft released STATE-Bench on May 19, 2026, evaluating memory systems through stateful enterprise tasks, repeated runs and user interaction.
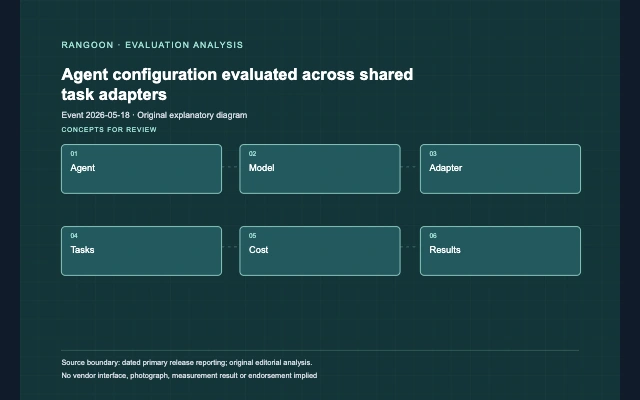
Read analysisIBM Research launched the Open Agent Leaderboard on May 18, 2026, reporting quality and cost for full agent systems across shared benchmarks.
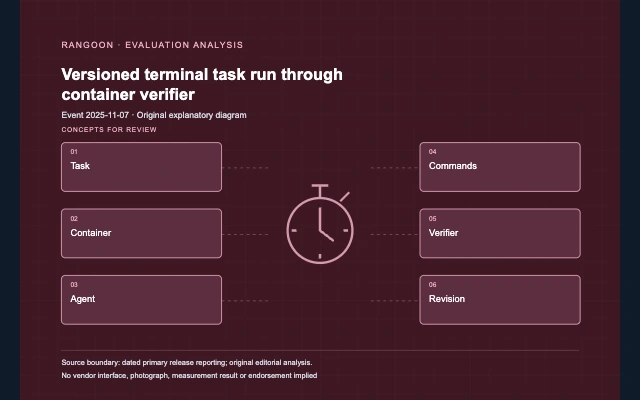
Read analysisTerminal-Bench released version 2.0 and Harbor on November 7, 2025, rebuilding terminal-agent tasks around stronger task verification.
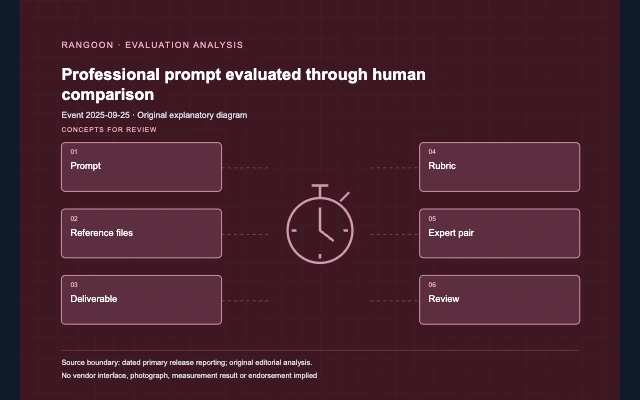
Read analysisOpenAI introduced GDPval on September 25, 2025, evaluating model deliverables across 44 occupations with expert comparison and a public gold subset.
Read analysisMeta introduced ARE and the Gaia2 benchmark on September 22, 2025, focusing agent evaluation on dynamic, asynchronous environments.
Read analysisOpenAI released HealthBench on May 12, 2025, a public benchmark of 5,000 health conversations scored against physician-created rubrics for model evaluation.
Read analysisAmazon introduced SWE-PolyBench on April 23, 2025, with 2,110 repository issues across Java, JavaScript, TypeScript and Python.
Read analysisOpenAI released BrowseComp on April 10, 2025, with 1,266 short-answer tasks designed to test persistent web browsing and verification.
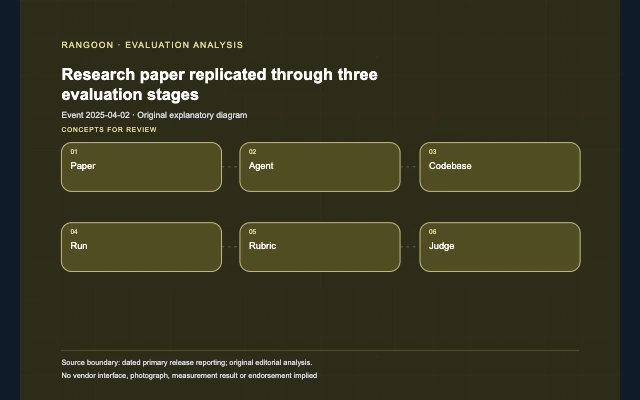
Read analysisOpenAI released PaperBench on April 2, 2025, using ICML papers, hierarchical rubrics and an open implementation to evaluate research replication.
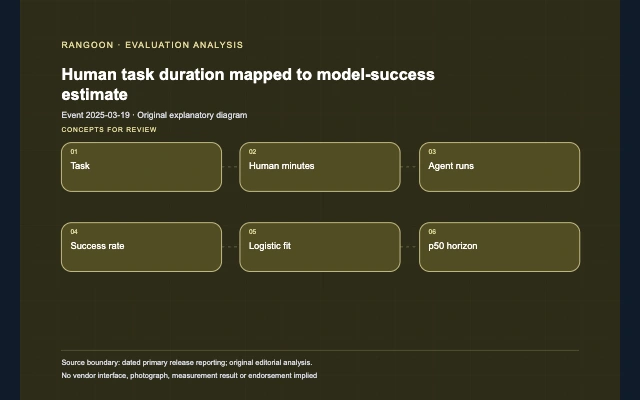
Read analysisMETR published its time-horizon study on March 19, 2025, relating agent success to expert human task duration across multi-step tasks.
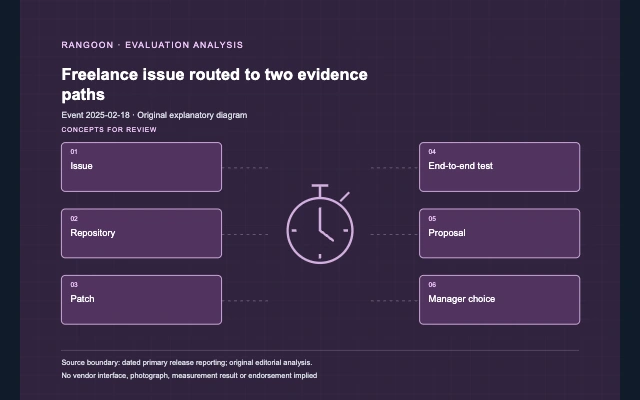
Read analysisOpenAI introduced SWE-Lancer on February 18, 2025, using freelance software tasks, end-to-end tests and manager-choice evaluations.
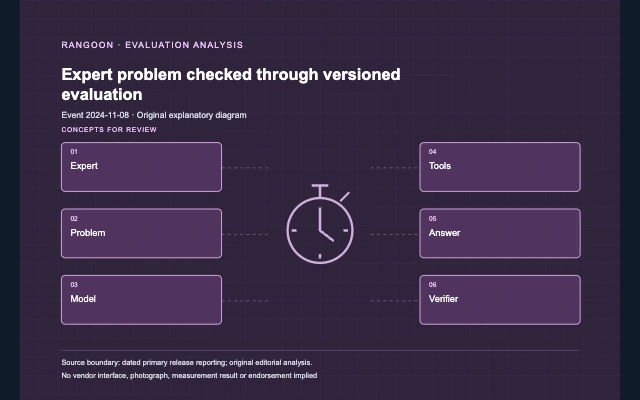
Read analysisEpoch AI introduced FrontierMath on November 8, 2024, pairing original expert mathematics problems with automated answer verification.
Read analysisMicrosoft Research introduced Magentic-One on November 4, 2024 as a generalist multi-agent system, reporting benchmark comparisons and publishing technical details.
Read analysisOpenAI introduced the SimpleQA factuality benchmark on October 30, 2024, using short fact-seeking questions and source-supported reference answers for tractable grading.
Read analysis